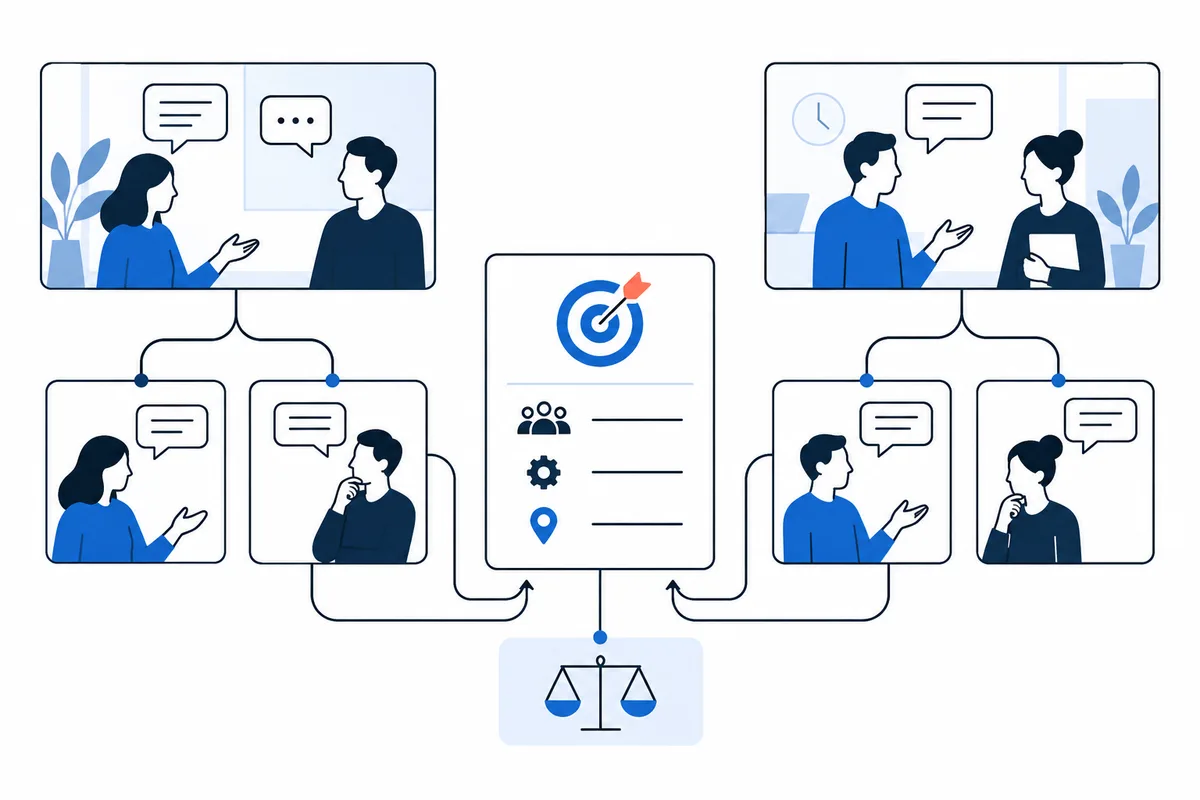
Realistic situations help when they supply information needed for a specific emotional judgment. More detail alone does not improve measurement: the instructions and scoring must make clear what the answer represents. Treat a scenario response as a prompt for reflection, then choose one behavior to observe in a real conversation.
A scene earns its place when it supplies the cue
An emotional situation belongs in an EQ item when the reader needs it to know what emotional evidence to consider. A bare prompt such as “What should you do?” leaves the task underspecified: the answer could depend on recognizing an emotion, interpreting why it arose, managing one’s own reaction, or responding to another person. A situation-based item gives just enough context to make the intended judgment visible. The scene is doing measurement work when removing a detail would change what the question is asking the respondent to notice or decide.
Consider this illustrative design example, not an observed event: a shared task is late, and a colleague’s message sounds sharp. If the item is meant to ask whether the respondent notices possible frustration, it needs a cue that makes frustration a reasonable interpretation, while leaving room for uncertainty. If it asks whether the respondent would clarify a constraint before replying, the prompt needs enough information to make a constraint plausible. A question about regulating a reply needs to establish that the respondent may feel provoked; one about responding to the colleague’s concern needs to say what concern has been expressed. These are different judgments, even though they can occupy the same work exchange.
The item should not settle the situation by supplying a single socially polished response. A direct question may be useful when a deadline is genuinely blocked; a pause may matter when an immediate reply would escalate tension. If the prompt asks for likely behavior, it should elicit the respondent’s own prediction. If it asks for an effective response, it should make the aim clear enough that an answer can be judged against that aim. Without this distinction, a scene may invite respondents to guess the writer’s preferred manner rather than show the emotional judgment the item was designed to elicit.
The 2013 study “Development and Validation of a Situational Judgment Test of Emotional Intelligence” illustrates how an EI instrument can be built from emotional situations. Its development began with 80 situations, each paired with three response alternatives; an initial sample of 213 participants produced a 46-item version and a three-factor structure described as using one’s own emotion, sensing others’ emotion, and understanding emotional context. Those results show that situation-based EI measurement can be developed around distinguishable emotional judgments. They do not establish that realistic scenes are required or superior for every EQ item. The design question remains specific: does this scene supply a cue the intended judgment actually needs?
A useful scene is therefore less like a short story than a carefully bounded task. It gives the respondent enough interpersonal information to understand what is at stake, but does not smuggle in a preferred personality, workplace convention, or answer through decorative details. When a scene clarifies the emotional cue and the question names the judgment, the respondent can engage with the intended problem. Whether adding more description improves measurement is a separate empirical question.
Sources: Development and Validation of a Situational Judgment Test of Emotional Intelligence
More detail can leave the measurement unchanged
A longer, more vivid prompt can feel more realistic without eliciting better evidence about the intended construct. Those are separate claims. Realism is a reader’s impression that a scene resembles life; measurement depends on whether the response reflects the judgment the item is meant to capture. A scene can gain names, office details, a long history, and emotional color while leaving the decision unchanged. It can also omit one crucial fact—who owns the blocked task, for example—and make two respondents answer different questions because they infer different stakes.
The 2020 study “Effects of situation descriptions on the construct-related validity of construct-driven situational judgment tests” tested whether situation descriptions changed construct-related validity in personality SJTs. In a within-subjects experiment with 158 participants, versions with and without situation descriptions showed almost no difference in that validity evidence. Conscientiousness was the reported exception: its convergent correlation was higher for the version without descriptions. The result cuts against a blanket design rule that adding a realistic setting automatically strengthens what an SJT measures.
The boundary of that finding matters. The study examined construct-driven personality SJTs, not an emotional-intelligence instrument, and its abstract-level report does not decide what context a particular EQ item requires. It cannot tell us that emotional context is dispensable when the target task depends on interpreting an emotional cue. If a prompt asks whether a terse reply might signal frustration, some wording has to show what was said and what preceded it. A description experiment in another domain cannot determine whether those details are necessary for that specific judgment.
The practical distinction is between information that changes the judgment and information that only decorates the scene. For an item about a late handoff, a stated deadline may matter if urgency is part of the intended judgment. A colleague’s role may matter if authority affects which responses are available. A paragraph about the office layout or the team’s history may add color without changing what a reasonable respondent would infer. Conversely, cutting the only clue that distinguishes frustration from confusion can make the item shorter while making its target less legible. The question is not how much context is present, but what work each detail performs.
An editor can apply a simple test derived from this comparison: if this detail were removed or changed, could a reasonable answer to the intended question change? If yes, the detail may be carrying relevant context and deserves scrutiny for clarity. If no, it may be scenic material that can be cut. This is an editorial rule of thumb, not a validated instrument checklist; it does not replace item testing. It directs attention to the link between the scene and the judgment, where an item can otherwise feel convincing while asking respondents to rely on information the score is not supposed to represent.
For EQ item design, the experiment supports skepticism toward “more realistic is always better,” while leaving open the case for context that defines an emotional cue. A concise item may be preferable when the target is clear without a scene. When the respondent must interpret an interaction, context can make the task answerable—but extra narrative does not earn its place merely by sounding lifelike.
What judgment does the situation make visible?
An emotional situation makes a particular judgment visible only when the item identifies what the respondent is meant to do with its cues. In an illustrative disagreement over a delayed handoff, a colleague says, “I still don’t have the figures I need, and the deadline is tomorrow.” That statement can support several different tasks. A respondent might notice that the colleague sounds frustrated, consider whether the frustration comes from urgency or from feeling left out of the process, regulate an impulse to defend the delay, or choose a next response. These operations can occur in the same exchange, but an item cannot treat them as interchangeable evidence.
If the question asks what emotion the message suggests, the item tests an inference from an expressed cue. The wording should include the colleague’s statement and enough surrounding information to distinguish frustration from, for example, a neutral request for a status update. The respondent is interpreting what is communicated, not reading the colleague’s mind; a good prompt leaves the limits of the cue intact. Without the words or tone that carry the signal, the respondent may be guessing from a generic label such as “disagreement.” Adding a detailed account of the project’s history would not necessarily make the emotional inference clearer.
A different item can use that same handoff to ask what the respondent would likely do. Now the target is a prediction about the respondent’s own response: perhaps they would ask which figures are missing, explain what delayed their part, or wait before replying. The prompt should preserve enough of the exchange to make that prediction meaningful, while avoiding a cue that practically dictates a socially approved choice. A further version could ask which action best serves a stated conversational aim, such as identifying the blocker while keeping disagreement possible. That asks for judgment about a goal-directed response, not a forecast of personal conduct.
Relationship and stakes belong in the scene when they change the judgment. Whether the colleague is a peer or someone dependent on the respondent’s work may matter if authority shapes the available response. The deadline matters if urgency is part of the task. A prior breach of trust matters only if the question is meant to involve that history. For a narrow emotion-recognition item, such facts can be noise; for a question about how to proceed, omitting them may leave respondents to imagine different conversations. The prompt should supply what lets them answer the same question, not everything that could make the scene feel like a complete story.
This is why realism is a design choice tied to the item’s target. A scene can ask respondents to notice a cue, interpret its possible meaning, manage a first reaction, or select a response for a named purpose. Each requires different information. If the item combines several operations, its score becomes harder to interpret because an answer may reflect one judgment while the writer intends another. The useful editorial question is therefore specific: what emotional judgment should this situation elicit, and which details make that judgment answerable? A vivid backstory that adds workplace familiarity without changing the requested judgment may make the task longer while measuring something incidental.
What answer is the item actually asking for?
An item can describe the same delayed handoff and collect two different kinds of answer, depending on its instruction. A behavioral-tendency instruction asks what the respondent would likely do; the answer is a self-prediction. A knowledge instruction asks the respondent to judge which response is effective or appropriate; the answer reflects a judgment against some criterion. The distinction matters because an item that asks what someone would do should not be interpreted as if it had asked what they know to be effective. A realistic scene cannot resolve ambiguity in the instruction itself.
Suppose a colleague says the figures are late and the deadline is tomorrow. Asked, “What would you most likely do next?”, one person might predict that they would explain the delay, another that they would ask what is still needed. Either answer describes a forecast about the respondent, not a record of what they actually did during pressure. The answer may reflect their self-view, their reading of this particular scene, or the response options available in the moment. Even a carefully written item cannot turn a prediction into direct observation of a future conversation.
Change only the instruction and the task changes: “Which response would best help identify the blocker while preserving room for disagreement?” The stated aim gives respondents a basis for judging effectiveness. They might consider asking which figures are missing, acknowledging the deadline, or first checking whether a dependency prevented delivery. The prompt need not imply that one manner—warm, calm, direct, or conciliatory—is always emotionally skilled. An answer is defensible in relation to the named aim and facts supplied. Without that aim, respondents may infer different standards: speed, relationship repair, accountability, or avoiding conflict. Their choices would then be difficult to compare as answers to one question.
The 2007 meta-analysis “Situational Judgment Tests, Response Instructions, and Validity: A Meta-Analysis” examined instruction types in personnel-selection SJTs. It reported that knowledge instructions were more correlated with cognitive ability, while behavioral-tendency instructions were more correlated with personality constructs. The meta-analysis found little moderation of criterion-related validity by instruction. For item writers, this is a reason to make the requested response type explicit and keep it aligned with the interpretation they intend; it is not evidence that one instruction is universally superior for EQ reflection. The source concerns selection tests broadly, not a validation study of this profile or this particular handoff item.
That boundary also helps explain why “best response” can be an unfairly vague instruction. If a scoring key assumes that the author’s preferred conversational norm is obvious, respondents may be rewarded for sharing that norm or recognizing the test writer’s convention. Naming the aim makes the judgment inspectable: the respondent can see whether a response addresses the blocker and leaves space to disagree. A likely-action prompt has a different purpose and should be interpreted as a report of what the person thinks they would do. In neither case does the answer alone establish how they would behave in a live exchange, where timing, authority, competing duties, and the other person’s reply can alter what is possible.
These instructions can therefore sit beside the same realistic situation without producing equivalent evidence. Writers should decide first whether they want a self-prediction or an effectiveness judgment, then phrase the scene and response options to serve that task. The distinction does not rank personal tendency below knowledge, or make a stated aim automatically correct. It clarifies what an answer can mean and prevents an item from silently switching from “what would you do?” to “what should a person do?” during scoring or interpretation.
Sources: Situational Judgment Tests, Response Instructions, and Validity: A Meta-Analysis
A plausible answer key still needs an argument
A key can call one response more effective only after the item says what the response is meant to accomplish. “Which answer is best?” leaves the standard hidden: a respondent might prioritize finding the missing information, acknowledging the strain, setting a boundary around an unrealistic deadline, or repairing a damaged exchange. Those aims can pull in different directions. A score that rewards one option without naming the judgment behind it risks measuring how closely someone guesses the writer’s conversational preference. The scene may be vivid and the choice plausible; neither fact explains why the key should award more credit.
Start with the target judgment and the outcome the item asks the respondent to serve. If the prompt concerns recognizing another person’s concern, an answer that identifies the concern has a clearer relation to the target than one that merely sounds friendly. If it asks how to move a blocked task forward while keeping disagreement possible, an answer may need to surface the obstacle and leave room for a reply. A different item could make immediate accountability its aim. Each is a defensible design choice when the wording gives respondents that same aim; none establishes a universal ranking of warmth, directness, calm, or openness as emotional intelligence.
Competing priorities should appear in the prompt when they are part of the judgment. In an illustrative delayed-handoff item, suppose one response asks what is still needed, another acknowledges the colleague’s frustration, and a third states a limit on what can be finished by tomorrow. Those options differ in what information or goal they address. A scoring rationale would need to explain which requested judgment makes one response more relevant, and why the other priorities do not answer that particular question as well. It should not rely on a smiling face, open posture, or agreeable tone as shorthand for the winning answer; demeanor alone does not establish what a person understood or accomplished.
That rationale also gives the writer a way to inspect the wording. Would respondents know whether they are being asked to identify a concern, make progress, protect a boundary, or repair the exchange? If a reasonable reader could choose different aims from the same prompt, the key may be scoring an assumption that the item never stated. Rewriting the question or adding a consequential fact can make the decision more consistent. This is a design argument, not evidence that reviewers or respondents have agreed on the key; such agreement and the quality of the resulting score require their own evidence.
The 2025 meta-analysis “The Validity of Single-Response Situational Judgment Tests: A Nomological Network Meta-Analysis” reported an association between studied single-response SJTs and job performance: the corrected estimate was rho=.20, with a 95% confidence interval of .12–.28. That result supports a bounded point: responses in this format can relate to a job-performance criterion in the studies examined. It does not show that a particular interpersonal option is objectively correct, or that the key for an emotional-skills reflection item is valid. AERA’s page for “Standards for Educational and Psychological Testing” describes the joint AERA/APA/NCME publication as addressing technical and professional issues in test development and use; the page does not validate this item or provide an item-level scoring rule. The defensible answer key therefore has to show its reasoning from the prompt’s stated judgment, not borrow authority from a plausible scene or polished response.
Sources: The Validity of Single-Response Situational Judgment Tests: A Nomological Network Meta-Analysis; Standards for Educational and Psychological Testing (2014 Edition)
What validation evidence can and cannot travel?
A validation result answers a question about a particular test, population, response format, criterion, and use. Before carrying it into an ordinary workplace conversation, ask how closely those parts match the claim you want to make. The systematic review “Situational judgement test validity for selection: A systematic review and meta-analysis” examined SJTs used in medical-applicant selection. Its result is relevant to evidence about that selection setting. Reading it as a direct estimate of how one employee will respond in a tense meeting changes the population, outcome, and purpose all at once.
The review included 30 studies, of which 26 contributed validity correlations. Its random-effects pooled association was .32, with a 95% confidence interval from .26 to .39. The authors also reported high heterogeneity (I²=96.5%) and moderate overall risk of bias. The pooled association is meaningful evidence in the literature the review studied; the variation among results and the review’s bias assessment qualify how simply it can be summarized. The estimate describes an aggregate relation between selection-test results and criteria across included studies. An association does not show that the test response caused later performance, and a pooled value does not describe every study equally. The high heterogeneity makes that distinction especially relevant when someone wants to apply the summary to a new setting. It is not an individual’s probability of handling a disagreement well, a personal forecast for a future conversation, or a measure of emotional growth.
The distinction becomes practical when someone sees an SJT result and wonders what it says about a meeting with a colleague. First identify what the criterion was: success in an applicant-selection context is not the same outcome as noticing a cue, regulating a reply, or repairing a working relationship in a particular exchange. Then check whether the respondents and response format resemble the person and assessment being interpreted. Finally, keep the use in view. Evidence that helps evaluate selection cannot, by itself, establish that an educational reflection profile diagnoses a stable capacity or predicts what will happen in a live conversation.
The review itself points toward a closer workplace outcome: its authors call for robust criterion measures that capture typical interpersonal performance at work. That recommendation matters because the meaning of a score depends on the outcome used to connect test responses with behavior. A criterion designed for selecting medical applicants may be consequential and appropriate for that purpose while leaving a different question unanswered: how does a person usually handle disagreement, feedback, or repair with colleagues? The gap is a reason to specify the intended interpretation and seek matching evidence, not to discard the findings the review actually reports.
For an individual reading a scenario result, the warranted conclusion is narrow but useful: it records an answer to a described situation, while the selection review supplies evidence about associations in its own research setting. The review did not test whether completing the current Emotional Skills Profile improves collaboration, and its pooled estimate cannot supply that missing result. In a meeting, someone might use the answer as a prompt to notice how they approach a disagreement, but whether they ask a question, pause, or set a boundary depends on the exchange and what the other person says. Interpreting a score as a personal forecast would exceed the evidence. Matching the studied population, response format, criterion, and intended use is the necessary first check before drawing a broader conclusion.
Sources: Situational judgement test validity for selection: A systematic review and meta-analysis
Whose situation feels real, and to whom?
A scenario can be clear in one language and still change its meaning when translated. The International Test Commission’s *The ITC Guidelines for Translating and Adapting Tests (Second Edition)* treats adaptation as work that extends beyond replacing words: it includes development, empirical confirmation, administration, score interpretation, and documentation. Equivalence means that versions support comparable interpretations for their intended use. It is an evidence question, not a quality reviewers can settle simply by deciding that a translation reads smoothly.
The guideline’s structure suggests practical editorial questions for an emotional situation. Does the wording preserve the interpersonal force of the exchange—whether a remark sounds like a request, a warning, or an invitation to explain? Does the respondent know enough about the relationship and authority involved to judge what is happening? Does an answer option assume that speaking openly, challenging a decision, or asking for time is safe and available? These are prompts derived from professional guidance, not reported findings about how any particular language group interprets emotion.
A scene about disagreeing with a supervisor illustrates why context needs scrutiny. If the item asks how to respond to a concern, the supervisor’s role may affect which actions are realistically available. Removing that fact could leave respondents to imagine different levels of risk or permission. Yet retaining workplace shorthand that only some readers recognize can make familiarity with a local convention part of the task. An editor can ask whether changing or removing a detail would change the intended judgment, then revise wording that makes the answer depend on an unstated assumption. This is a review method, not proof that a particular version works equally well.
These prompts should be applied to the whole item, including its answer choices and instructions. An option that says “raise the issue directly” may sound straightforward while leaving unclear whether the respondent can speak in the meeting, needs to use a formal channel, or has responsibility for the decision. If the intended skill is recognizing concern, that procedural choice may distract from the emotional cue. If the task asks how to respond under a stated constraint, the constraint belongs in the scene. Reviewers can mark where wording, role assumptions, or access to a response needs clarification; their comments help guide revision, while comparison of score meaning remains a separate empirical question.
The ITC guidelines also distinguish development and review from empirical confirmation. A careful translation can reveal ambiguous wording; a reviewer’s positive reaction can flag a scene that feels accessible. Neither alone demonstrates that scores from two versions mean the same thing. That requires evidence suited to the proposed comparison and use. At the same time, context that reflects a particular workplace relationship is not automatically bias: it may supply information essential to the judgment. The question for an item writer is whether that context defines the emotional task or quietly asks respondents to share an assumed convention.
Sources: The ITC Guidelines for Translating and Adapting Tests (Second Edition)
Use the answer to choose an observation
A scenario answer is most useful as a question to carry into one real exchange. Choose a behavior specific enough to notice, such as asking what concern sits behind a disagreement. In an upcoming conversation, pay attention to whether you ask, what the other person says next, and what made the response easier or harder. Afterwards, compare the exchange with your scenario answer: did you act as expected, or did the situation change what felt possible? This is practical reflection, not evidence that the exercise itself changes behavior. Keep the observation narrow: whether you asked the question, what answer you heard, and whether you followed up before defending your position. That gives you something concrete to compare, rather than a broad label such as “good at conflict.” during that specific exchange.
The Emotional Skills Profile offers one private starting point for that reflection. It has 32 items and keeps summaries of recent behavior separate from judgments on authored scenarios. It is an educational profile; neither component has validated norms. You can explore it at [/assessment](/assessment) if having both kinds of prompts would help you choose what to observe. An answer can guide attention, but it does not prove how you will act next time. A live interaction also depends on the other person’s response and the constraints around the conversation.
Sources: Emotional Skills Profile
Questions readers ask
Can a realistic EQ test scenario predict how I will behave at work?
It records your answer to a described situation, not what you will do in a changing conversation. Use it to choose one behavior to notice in an actual exchange.
Sources
- Development and Validation of a Situational Judgment Test of Emotional Intelligence
A specific EI SJT was built from situations and response alternatives and studied for its factor structure and associations; use as a concrete example of scenario-based EI instrument development, not a general rule about realism.
- Effects of situation descriptions on the construct-related validity of construct-driven situational judgment tests
A within-subjects study of construct-driven personality SJTs found nearly no difference in construct-related validity between versions with and without situation descriptions, with conscientiousness as an exception; this challenges the assumption that richer context automatically improves measurement.
- Situational Judgment Tests, Response Instructions, and Validity: A Meta-Analysis
In SJT personnel-selection literature, behavioral-tendency instructions ask what respondents would likely do and knowledge instructions ask them to evaluate effectiveness; the meta-analysis reports different construct correlates but little moderation of criterion-related validity by instruction.
- The Validity of Single-Response Situational Judgment Tests: A Nomological Network Meta-Analysis
A 2025 random-effects meta-analysis of single-response SJTs covered 20 samples and 3,685 participants and reported a job-performance association (abstract summary: r=.18 uncorrected, corrected estimate reported in the article); most studies used low-stakes laboratory settings, limiting transfer to ordinary collaboration or the Emotional Skills Profile.
- Situational judgement test validity for selection: A systematic review and meta-analysis
For medical-applicant selection, the review included 30 studies, with 26 contributing validity correlations; random-effects pooled association .32 (95% CI .26–.39), high heterogeneity I²=96.5%, moderate overall risk of bias, and authors called for robust criteria of typical interpersonal workplace performance.
- The ITC Guidelines for Translating and Adapting Tests (Second Edition)
The professional guidelines treat adaptation as including preconditions, development, empirical confirmation, administration, score interpretation, and documentation; translation or a locally familiar scene alone cannot establish score equivalence.
- Standards for Educational and Psychological Testing (2014 Edition)
AERA identifies the joint AERA/APA/NCME Standards as guidance on technical and professional questions in test development and use; supports the general principle that evidence must match the intended interpretation and use, not validation of a specific item or instrument.
- Emotional Skills Profile
The assigned product is a private 32-item educational Emotional Skills Profile. Its report separates recent-behavior summaries from judgments on authored scenarios; neither component has validated norms and it is not a standardized ability test.
Apply it to the real situation
Turn an EQ result into one behavior to observe
From this guide: A scenario can focus your attention on an emotional cue or response choice; the next step is noticing how that behavior appears in a conversation that matters to you.
The Emotional Skills Profile offers a structured starting point for examining recent emotional habits and judgments on authored scenarios. Its report keeps those parts separate. Use the profile to identify a behavior worth observing, then notice what happens when you try it in an ordinary conversation.