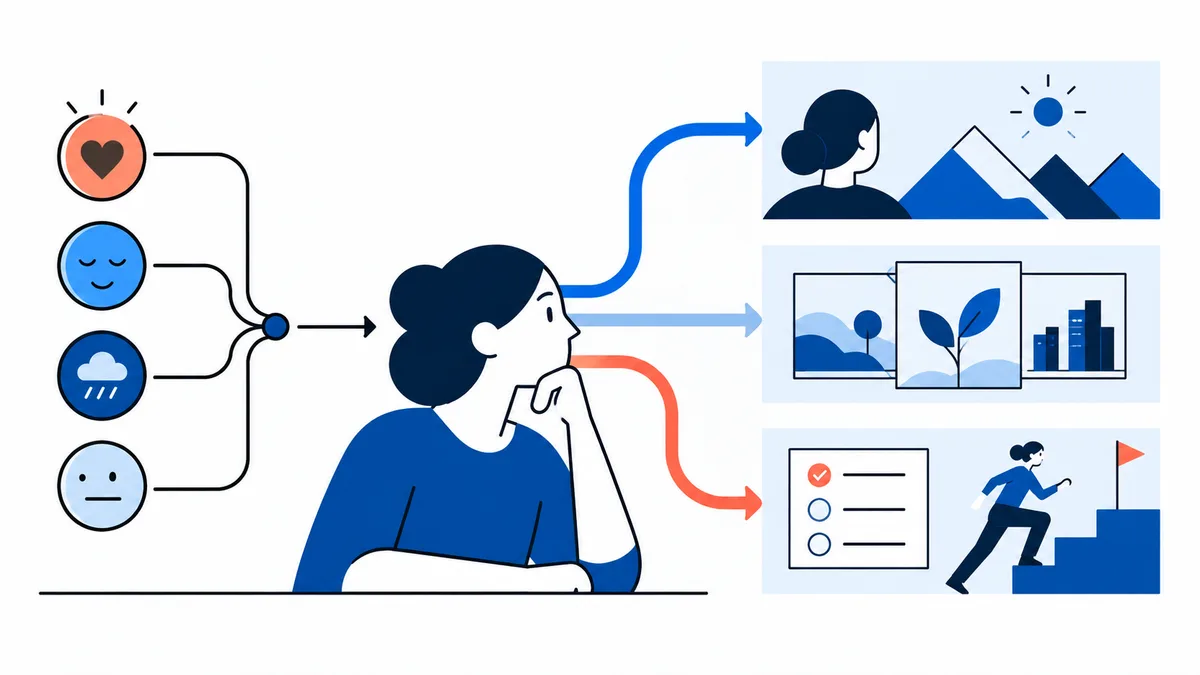
On the Schutte scale, emotion use refers to bringing emotional information into thought and action. The questionnaire records how people describe their usual tendencies; it does not observe their behavior. A utilization subscore depends on the form and scoring model, so check those details before interpreting the label.
What does the scale mean by emotion use?
Emotion use describes the theoretical idea that feelings can contribute information to thinking and action. In the model discussed by The Measurement of Emotional Intelligence: A Critical Review of the Literature and Recommendations for Researchers and Practitioners, emotion may guide attention, help a person consider alternatives, or inform a choice. The phrase names a proposed way emotional information can enter reasoning; it does not, by itself, establish that a particular response was effective. This is why the phrase concerns a possible contribution of emotion to cognition, rather than a promise that emotion should overrule evidence or settle a choice.
For illustration, before a difficult work conversation, unease might prompt someone to check whether they have overlooked a concern. The feeling has influenced attention and the next step. That example explains the idea; it is not evidence about how any respondent behaves, nor does noticing unease guarantee a sound decision.
On the Schutte Self-Report Emotional Intelligence Test, the label must be read through the questionnaire’s method: respondents describe themselves. A result therefore reflects their self-view on items associated with emotion use. It is not an observation of a meeting or a performance score showing that feelings were used skillfully. The distinction is central: the branch is a theoretical description of emotion’s role in thought, while the answer sheet records a person’s report about themselves.
What did the original 33-item score represent?
The original Schutte Self-Report Emotional Intelligence Scale was built as an overall self-report measure. Development and Validation of a Measure of Emotional Intelligence describes how the researchers began with 62 candidate statements based on an emotional-intelligence model, then used responses from 346 participants in their development analysis to select a 33-item scale. The intended result was a total score representing the broad construct as the authors operationalized it, rather than a separately established score for each theoretical branch.
That distinction matters when a later report gives a number specifically for emotion use. An overall score combines responses across the selected item set according to the instrument’s scoring procedure. A branch score makes an additional claim: that a subset of items can be interpreted together as a distinct and sufficiently supported dimension. The fact that the original theory described branches, or that candidate statements were written with those ideas in mind, does not alone demonstrate that every branch has its own dependable score.
The original paper’s abstract reports reliability and validity studies for the resulting total measure. In ordinary terms, reliability concerns whether scores show consistency under the conditions examined; validity evidence concerns whether the interpretation made from those scores has support. The abstract’s report is relevant to the overall scale the paper developed. It should not be silently transferred to a later utilization subscore, a different translation, or a changed item set, because those are distinct score interpretations that need evidence of their own.
The development sequence also explains why the title and score format matter. A questionnaire can draw on a multidimensional theory while its initial statistical analysis supports one broad score more clearly than several narrow ones. The 62-item pool records the range of ideas considered; the 33-item outcome records the measure retained after analysis. Neither number is a count of proven subskills. For readers comparing a report with the original scale, the useful first question is whether the reported result is the instrument’s overall score or a later branch-level calculation.
So the original total and an emotion-use subscore should not be treated as interchangeable evidence. The former is the scale’s stated overall result, with initial reliability and validity findings reported for that interpretation. The latter asks whether responses attributed to one theoretical area form a distinct score that can carry its own meaning. Establishing that narrower interpretation requires examining how the particular version was scored and tested; it cannot be inferred just from the original scale’s development history.
Sources: Development and Validation of a Measure of Emotional Intelligence
Why did later researchers debate the subscales?
The debate concerns whether the questionnaire’s responses can be divided into distinct scores that correspond to the theory’s branches. In An Examination of the Factor Structure of the Schutte Self-Report Emotional Intelligence Scale via Confirmatory Factor Analysis, the researchers revisit the structure reported for the instrument and question how strongly it supports that division. Their critique matters because a label such as “emotion utilization” can look like a direct measurement of a separate capacity, even when the statistical basis for treating its items as one score is unsettled.
Factor structure means the pattern of relationships among items: which responses tend to vary together, and whether those clusters support the proposed dimensions. It is a question about the organization of scores, not simply about whether each item sounds relevant to a branch. A question may have been written to represent emotion use yet still overlap statistically with items assigned elsewhere. Conversely, an item group that clusters in one analysis does not automatically show that the underlying skill is independent or that it predicts behavior outside the questionnaire.
The article’s accessible account describes four extracted components, but says only the first had an appreciable number of item loadings above the authors’ criterion. A loading is the statistical association between an item and a component; a stronger pattern across multiple items would make a distinct component easier to interpret. The critique therefore identifies a gap between naming four theoretical areas and obtaining clear item groupings for each. It does not require the conclusion that the whole scale is meaningless; it makes the narrower point that the existence of four concepts does not itself establish four comparably clear scores.
That gap helps explain why later scoring accounts could differ. Researchers may test whether items organize according to the original theory, a more compact structure, or another arrangement supported by their data. A utilization label can consequently reflect a later analytic choice about which items belong together, rather than a score whose status was settled simply by the theory’s vocabulary. Readers should attend to the specific form and scoring model behind a branch result, because two reports using the same broad instrument name may not be making the same dimensional claim.
The critique is one methodological analysis, and the accessible material does not settle every later model or adaptation. Its contribution is to make the subscale question testable: does the proposed grouping appear in the data under a stated model, and how clearly do the items support it? Later studies can provide evidence for particular structures in particular samples. Their results need to be considered on their own terms, rather than treated as automatic proof that the initial ambiguity vanished everywhere.
What does the American college validation settle?
A later confirmatory study found support for one proposed structure in its sample. Validation of the Schutte Self-Report Emotional Intelligence Scale With American College Students compared previously proposed factor models using online responses from 404 American college students. The authors report that the two-level model proposed by Ng and colleagues fit best among the models they tested. This is a meaningful update: the structure was not merely assumed from the branch names; a specified candidate was compared with alternatives in a defined dataset.
The sample description is part of what that result means. The 404 respondents included 322 women, and 88.9 percent were White. The study thus provides a confirmatory comparison in an online American college sample with a notable demographic concentration. Its conclusion has a clear home: among the candidate models evaluated with these students’ responses, the two-level proposal performed best. That finding deserves to count as evidence for the model in this setting, rather than being waved away because the original dimensional question was debated.
“Fit best” is a relative statement about the alternatives in the comparison. It means the authors found that candidate more consistent with the observed response pattern than the other proposed models they tested. It does not mean every conceivable structure was tested, that the winning model fits perfectly, or that the same ordering would necessarily appear in a different population. The study moves the discussion from whether a proposed structure can receive confirmatory support to what that support covers: a particular comparison, version, and sample. A model can win a comparison even when the evidence is limited to the particular options and observations available; the ranking answers which tested account was strongest here, not whether it exhausts the ways emotional responses might be organized. That distinction gives the result proper weight without asking it to answer beyond its design.
This matters for a reader encountering an emotion-utilization score. A later model that performs well can make a branch-based interpretation more credible than item wording alone would make it. But the reported model comparison is not a direct demonstration that a utilization score independently captures a stable skill, nor does it establish what such a score means in a workplace conversation. Those are further interpretations. The study’s abstract supports a structural finding in the sampled students; translating that finding into a claim about an individual’s conduct would require evidence aimed at that different question.
The appropriate conclusion is neither to ignore the American study nor to treat it as universal confirmation. It supplies positive evidence that one proposed two-level arrangement can fit a specific college sample better than the competing arrangements examined. Whether that organization holds across age groups, demographic settings, or other versions remains outside what this one comparison can decide. The result narrows the uncertainty by identifying a supported candidate in context; it does not turn the instrument’s subscale structure into a context-free fact.
Sources: Validation of the Schutte Self-Report Emotional Intelligence Scale With American College Students
When does a utilization factor emerge?
The Spanish athlete study gives the utilization label a stronger basis in one defined setting. Emotional Intelligence in Sport: Validation of the Schutte Self Report Inventory (SSRI) in Spanish Athletes examined a Spanish adaptation with 2,091 athletes, ages 11 to 59, competing at regional, national, and international levels. Its reported structure included four dimensions, one of them utilization. A separate group of 67 athletes completed the measure again after 15 days. This is not a small illustrative sample or a factor inferred from item wording alone: the study tested an adapted instrument with a large, sport-specific group and reported a utilization grouping in its results. Its breadth matters when weighing what the factor result means: the group included athletes at different ages and competition levels, while every participant was still drawn from sport. The study consequently offers useful variation within that setting, not a sample of employees or a general cross-section of Spanish speakers. The retest group shows that the researchers also included a short-interval repeat administration; it does not change the population boundary of the main structural finding.
That result sits beside the American college validation without canceling it. The college study compared proposed models in online responses from 404 American undergraduates and found the Ng two-level model fit best among those tested. The Spanish study asks what structure appears for a Spanish adaptation in athletes; the college analysis asks which of several proposed structures best describes a particular American student sample. Population, setting, language form, and analytic comparison all differ. If the resulting structures do not line up exactly, the difference is information about where a score structure has been examined, not grounds to crown one population the universal test of the other. The contrast is not a simple translation contest: the participants differed in age and role, and only one validation was situated in sport. Even when studies begin from the same broad questionnaire family, the response patterns are observed under different conditions and tested against different structural proposals. A result from one group cannot be used to repair an apparent mismatch by assumption; the comparison instead points to the need to name the population and adaptation alongside any claim about the factor.
The Spanish finding therefore supports a bounded use of “utilization”: researchers using that Spanish sport-context form had evidence for treating responses as a distinct dimension in that study. It does not establish that the original English 33-item form, every translation, or a report encountered in ordinary work has the same dimension or scoring key. Nor does a factor label establish that an athlete—or a colleague—uses emotion effectively in action. A reader may take the result seriously while asking which version generated a score. The evidence makes the label more than a theoretical possibility in this adaptation; it does not detach the label from the instrument and group in which it emerged. In practice, a coach or athlete reading a report can treat the dimension as a prompt about how emotional information figures in sport-related self-description, then look to relevant behavior for interpretation. An office reader has less basis to assume the same subscore has already been established for workplace use. That is a boundary on transfer, not a reason to discard the sport study: its sample and finding make a clear contribution to the question of whether utilization can appear as a separable dimension at all.
What changes when an adaptation changes the items?
A shared scale name can conceal a different test. Psychometric Properties of the English and Malay Version of the Adapted Schutte Emotional Intelligence Scale studied an A-SEIS with 200 undergraduates at Universiti Putra Malaysia. The researchers retained the original 33 self-report items, translated and reviewed the adaptation for English and Malay use, and added ability-based items: six addressing understanding of emotions and twelve to the perception construct. The resulting form had 51 items and combined self-ratings with scenario and facial-expression responses. Its score therefore draws on more than a translated wording of the original self-report inventory. “English and Malay” describes the languages offered for this adapted work; it does not make the instrument identical to two language editions of an unchanged 33-item questionnaire. The researchers used forward and back translation and expert review, while also making substantive additions to content. Translation procedures address wording and cultural suitability; the new items separately broaden the measured material. Readers need both facts to understand why the familiar name alone cannot identify the score.
The adaptation also changes the map a reader might expect from the familiar branch labels. The article describes five dimensions in the instrument: perception, understanding, managing one’s own emotions, managing others’ emotions, and utilization. Its results report the adapted measure as suitable for tertiary education settings and future research. That conclusion belongs to the 51-item mixed form studied with those Malaysian undergraduates. It cannot by itself tell a reader that an original 33-item Schutte report has five equivalent dimensions, or that the two forms produce interchangeable utilization scores. A changed item set can change what a dimension contains and how a total or subscore is assembled. The distinction between a scale’s label and its operational contents is especially consequential here: “utilization” sits within a mixed instrument, while the paper’s broader score includes response formats absent from a self-rating-only form. A report that simply prints a branch name may leave unclear whether it aggregates only perceived tendencies or also answers to structured tasks. The study’s favorable conclusion about its intended setting should be read with those design features attached, rather than detached and cited as evidence for every Schutte-branded score.
Before comparing two reports, identify the form’s language, item count, and scoring description. A “utilization” heading is not enough to establish that both scores summarize the same responses: one may come from a self-report-only form, another from an expanded instrument that includes ability items and a revised construct map. Differences between their numbers could reflect those measurement choices as well as differences between respondents. The useful question is whether the report names the exact version and explains what its utilization score includes. Without that information, avoid importing the 51-item study’s structure or conclusions into the original form; ask the provider which version and scoring model produced the result. This check also prevents a false comparison when someone tracks results over time or discusses scores from different reports. A changed questionnaire may shift the meaning of a repeated label even if both reports use similar terminology. The article does not establish a conversion between the adapted score and original form, so a reader should not treat a difference as growth or decline on one common scale without documentation that the forms and scoring support that comparison.
What can self-report tell you that a performance task cannot?
The difference begins with what the respondent is asked to do. In The Measurement of Emotional Intelligence: A Critical Review of the Literature and Recommendations for Researchers and Practitioners, the authors distinguish self-report measures such as the Schutte scale from ability measures that present emotion problems and score responses. A self-report answer describes what a person believes they typically notice or do. An ability task samples how they respond to a defined problem under the task’s rules. One is a report of perceived habits; the other is performance on structured emotional reasoning. They can both concern emotion use without producing interchangeable evidence. The method matters as much as the topic: a question about what you usually do invites a different answer from a problem with a defined response.
The same review places these formats on different sides of a practical question. Someone rating their own habits may report that they use feelings to guide decisions, or may say that they find it difficult to do so. The answer can point toward a tendency worth checking in daily work, but it remains self-description. A performance measure such as the Mayer-Salovey-Caruso Emotional Intelligence Test (MSCEIT) instead asks a person to answer structured emotion problems. Measuring Emotional Intelligence with the Mayer-Salovey-Caruso Emotional Intelligence Test (MSCEIT) evaluates the test’s answer agreement, reliability, and factor structure. Those features concern how responses to its tasks are assessed; they do not turn the response into a record of what the person usually does at work.
Consider a disagreement in a project meeting. A Schutte-style self-view might prompt someone to notice whether they use irritation or concern as a cue to ask for more information, or whether they treat the feeling as proof that a colleague’s suggestion is wrong. That reflection identifies something to observe; it does not establish what happened in the meeting. An ability task can show how the person answered an emotion problem presented by the test, which adds information a self-description cannot supply. Yet a controlled task does not record the exchange, the missing context, or the choice made when colleagues disagreed. Neither format alone tells the reader how this particular meeting unfolded.
This distinction helps explain why a self-report result and a task result may differ without one automatically exposing the other as mistaken. The formats call for different responses, and the resulting scores answer different questions. A person may describe a habit confidently while responding differently to a structured problem; that gap itself needs interpretation rather than a quick verdict about honesty or competence. The critical review offers a measurement distinction, and the MSCEIT paper evaluates its structured method. Neither source establishes which score forecasts conduct in a particular workplace disagreement. Read the self-report as a clue about perceived typical behavior and the task as evidence about responses to its presented problems. To understand the meeting, the reader still needs to examine the observable exchange itself.
Sources: The Measurement of Emotional Intelligence: A Critical Review of the Literature and Recommendations for Researchers and Practitioners; Measuring Emotional Intelligence with the Mayer-Salovey-Caruso Emotional Intelligence Test (MSCEIT)
How should a utilization label change a work question?
Treat a utilization label as a hypothesis about where emotion may enter your reasoning. To examine it, separate five parts of one event: what happened, what you felt, what you concluded, what you did, and what followed that another person could observe. The point is to make a broad label specific enough to test against an ordinary decision. “I use emotion well” and “I let emotion take over” are conclusions; neither identifies the step where feeling affected judgment.
Imagine a hypothetical handoff in which a colleague’s update sounds unusually brief. You feel concern that a deadline may be at risk. Before deciding the colleague has ignored an important task, note the event (a short update), the feeling (concern), and the interpretation (the task may be late). Your action might be to ask which work remains and when it will be ready. The observable consequence is whether the answer provides information that changes the plan, or whether the concern had already settled your view before you asked. This example does not establish what any real colleague intended or how a real project would turn out; it shows the parts of a response you can notice.
The distinction matters because emotion can be useful as a signal without being proof of the story attached to it. Concern might direct attention toward a gap worth checking. If it instead closes the question before information arrives, the same feeling has shaped the decision differently. Looking back at the sequence lets you ask a narrow question: did the feeling lead to an inquiry, or did it harden into an assumption? Then consider what the other person actually said or did, rather than treating your initial interpretation as the outcome. If you cannot name an observable consequence, keep the interpretation provisional: the feeling may have flagged an issue, while the available evidence remains too thin to settle what it means.
This is reflective practice, not a validated scoring procedure. A single handoff may be shaped by role, urgency, or information unavailable at the time, so it supports an observation about that event rather than a general claim about stable capacity. The useful result is a more precise next observation: in another relevant exchange, notice whether concern helps you check a conclusion or makes the conclusion feel settled too soon.
What should you do with a utilization result?
Start with the report itself: find the instrument’s exact form, item count, and scoring key. A utilization label cannot tell you whether it comes from the original self-report scale, a translated or expanded adaptation, or a provider’s own grouping. If the form or scoring model is missing, ask the provider what responses make up the score before interpreting it. Until then, treat the label as a question to investigate, not a settled description of your ability.
Then choose one relevant interaction and one behavior to notice. For example, in a tense handoff, observe whether concern prompts you to ask what is unfinished, or whether you decide too quickly that the other person has failed. Record the feeling, your next action, and what the other person actually says or does. That gives a later reflection something concrete to examine; it does not turn one exchange into a new score or a verdict about your usual conduct.
If you want a different structured prompt for personal reflection, EQ Test’s separate 32-item Emotional Skills Profile is available at [/assessment](/assessment). It focuses on recent emotional behavior and authored situations; it is not a Schutte form or a conversion of its utilization result. The Schutte report remains the place to ask its provider how that particular score was produced.
Questions readers ask
What does emotion use mean on the Schutte test?
It describes bringing emotional information into thought and action, such as a feeling drawing attention to a concern. On the Schutte self-report scale, the result reflects how a person describes their tendencies; it does not show what they did in a particular situation.
Did the original 33-item Schutte scale include a utilization subscore?
The original development study describes a 33-item overall self-report measure. Utilization subscores come from later factor models and adaptations, so check which form and scoring approach produced a report.
How does the Schutte scale differ from the MSCEIT?
The Schutte scale asks people to describe their usual tendencies. The MSCEIT presents structured emotion problems and scores responses using its own method. They concern related topics but provide different kinds of information.
Sources
- Development and Validation of a Measure of Emotional Intelligence
The original Schutte paper developed a 33-item self-report scale from a 62-item pool and framed it around Salovey and Mayer’s model.
- An Examination of the Factor Structure of the Schutte Self-Report Emotional Intelligence Scale via Confirmatory Factor Analysis
A critique of the original development analysis explains that only the first of four extracted components had appreciable item loadings, complicating later claims that the original scale cleanly represented separate dimensions.
- Validation of the Schutte Self-Report Emotional Intelligence Scale With American College Students
In an online American college sample, the Ng et al. two-level factor model fit best among tested proposed models.
- Emotional Intelligence in Sport: Validation of the Schutte Self Report Inventory (SSRI) in Spanish Athletes
A Spanish sport-context validation reports a four-dimension solution including utilization among 2,091 athletes, with a separate 67-person retest sample.
- Psychometric Properties of the English and Malay Version of the Adapted Schutte Emotional Intelligence Scale
The tested 51-item English/Malay adaptation with Malaysian undergraduates changes the item set and construct coverage, so its results cannot simply be assigned to the original 33-item score.
- The Measurement of Emotional Intelligence: A Critical Review of the Literature and Recommendations for Researchers and Practitioners
The review distinguishes self-report measures such as Schutte from ability measures based on answers to emotion problems, whose methods target different kinds of information.
- Measuring Emotional Intelligence with the Mayer-Salovey-Caruso Emotional Intelligence Test (MSCEIT)
The MSCEIT validation paper evaluates answer agreement, reliability, and factor structure for a structured ability-test method.
Apply it to the real situation
Turn an EQ result into one behavior to notice
From this guide: A Schutte subscore may raise a question about how feelings enter your decisions; check that interpretation against a recent behavior you can observe.
The Emotional Skills Profile offers a separate, private reflection on recent behavior and authored scenarios. It is not the Schutte scale, and its results are not equivalent. Use it to explore your emotional habits and identify a behavior to reflect on next.