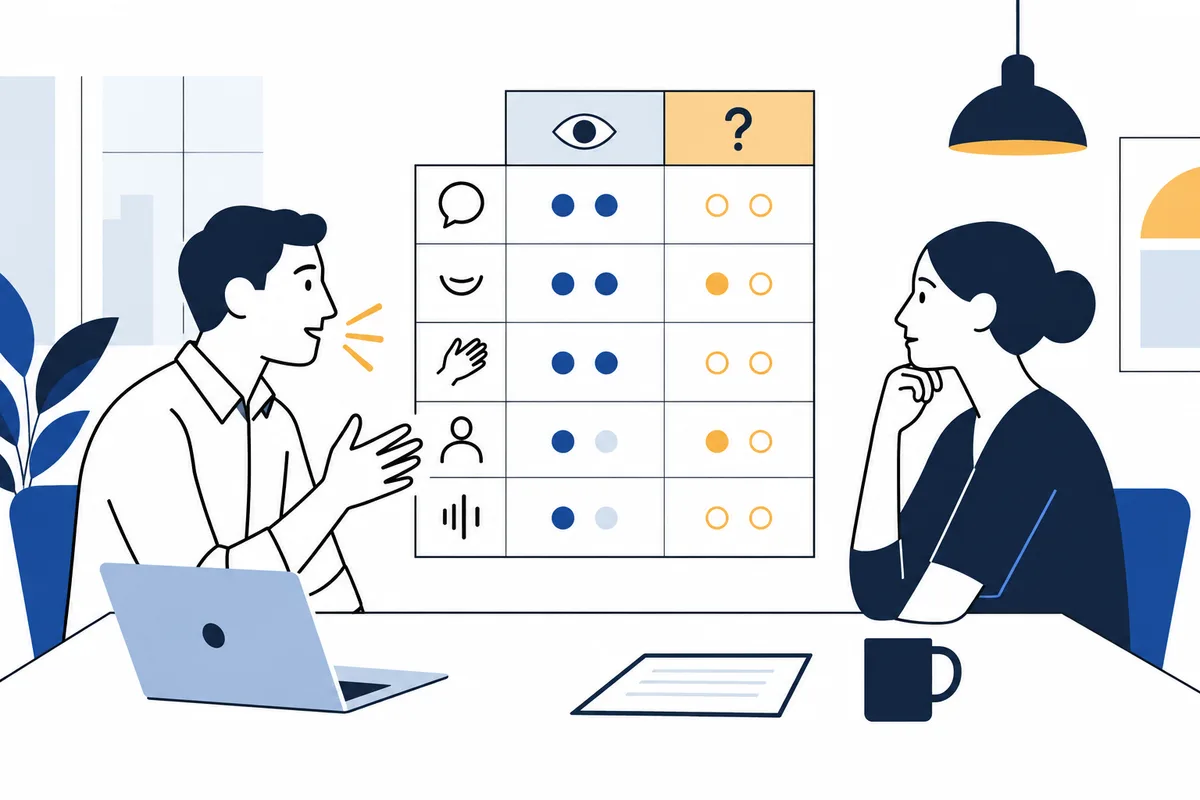
An emotion-recognition test can show how someone interpreted the cues and response options it sampled under its scoring rules. Workplace scenarios may add evidence about choices in designed work situations. Neither kind of result verifies what a colleague felt in one unscripted conversation. In a live exchange, describe what you observed, ask a neutral question, and update your interpretation from the reply.
What can an emotion-recognition test establish?
A test can show how someone performed when interpreting the cues it presented under its response and scoring rules. That is evidence about sampled task performance. It is not a transcript of what a colleague felt in one meeting. For a live exchange, treat the result as a starting hypothesis; observable behavior and a direct check carry the interpretation forward. The key question is not whether a score reveals a person’s hidden emotional truth, but what the test actually asked them to recognize and how it judged the answer. The result cannot fill that gap by itself.
Emotion recognition means identifying or judging emotion-related information from a specified stimulus. The stimulus might be an image, a moving face, or a described situation; the available labels and scoring rule shape what counts as a response. In the MSCEIT validation study, Mayer and colleagues reported that 21 emotion experts endorsed many of the same answers as 2,112 people in the standardization sample. Agreement was stronger for items with clearer answers, including some face-perception items. This supports a bounded claim: for those sampled items, the instrument had a defensible basis for scoring responses. It does not show that the keyed label exposes what a particular person privately felt in an unplanned workplace exchange.
A second example makes the task boundary visible. The Geneva Emotional Competence Test (GECo) uses actor-video clips for emotion recognition, while its other competencies use work-related situational judgment items. Its development paper reports five studies with 888 participants and high measurement precision across subtests, alongside expected correlations with other measures. Those findings describe performance on GECo’s designed tasks and the relationships reported in those studies. They do not turn a video response or a scenario choice into a record of a colleague’s feeling during a real conversation.
Keep three steps separate when applying any result. First, a person recognizes or labels information in the stimulus. Next, they infer what an actual speaker may be feeling, using cues that may differ from the test’s. Finally, they decide how to respond. A score speaks most directly to the first step, and a work scenario may provide evidence about choices in the second kind of designed task. Neither settles the third step in a particular meeting. Before acting on an apparent emotion, retain the score as evidence about the task, name the behavior you observed, and ask what additional information could confirm or revise your reading.
Sources: Measuring Emotional Intelligence with the MSCEIT V2.0; The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence
What does a recognition score actually measure?
A recognition score is a record of how a person answered a particular set of prompts under a particular scoring rule. In a face-labeling task, the stimulus might be a photograph or a brief clip, the response might be a choice among emotion words, and the score reflects how those choices compare with the test’s key. A result therefore speaks first to performance on that task. It does not show that the person can read every signal in an ordinary exchange, or that the keyed label gives direct access to what the person pictured privately felt.
The key itself matters. The 2003 study “Measuring Emotional Intelligence with the MSCEIT V2.0” examined whether 21 emotion experts and a standardization sample identified the same answers as correct. Its abstract reports that the experts and 2,112 sample members endorsed many of the same answers, with stronger agreement on items that had clearer answers, including emotional perception in faces. That is evidence that responses on those MSCEIT items could be scored with meaningful agreement. It is not a check against the inner experience of the person in a photograph, much less a coworker in a meeting. Agreement tells us how consistently people apply a key; what the key represents remains a separate question.
Tests can build that key in different ways. Some compare a response with answers endorsed by experts or by a larger sample. Others define a correct answer through a stated theory or scoring rule. A forced-choice item adds another constraint: the respondent must select from the labels supplied, even if the best description would be more qualified or absent. None of these formats is automatically useless. A fixed stimulus and consistent scoring can make comparisons clearer. But the reported ability is bounded by what the test showed, the options it offered, and how it judged them.
That boundary matters when the test uses posed expressions. In “Is There Universal Recognition of Emotion from Facial Expression?,” a 1994 review, Russell examined cross-cultural studies and raised concerns about their ecological, convergent, and internal validity. The abstract identifies forced-choice formats, within-subject designs, and preselected photographs of posed expressions among the methodological features that could shape findings. It reports that changing those methods sometimes produced less supportive results, while also concluding that facial expressions and emotion labels are probably associated. The review does not show that faces carry no emotional information. It shows why a score from selected photos and supplied labels should not be recast as a universal reading skill.
A still image removes timing and movement; a posed display may differ from an expression that arose during a real exchange. Even a moving clip leaves out the history, words, roles, and immediate stakes surrounding a workplace conversation. These differences do not invalidate a controlled test. They identify the conditions under which its result was obtained. Before using a score to think about work, check what was presented, whether the answer choices were fixed, how the key was set, and which conditions the test sampled. When those conditions differ from the conversation at hand, keep the conclusion at the task level and treat any guess about a colleague as something to check.
Sources: Measuring Emotional Intelligence with the MSCEIT V2.0; Is There Universal Recognition of Emotion from Facial Expression? A Review of the Cross-Cultural Studies
Why can the same cue carry different meanings?
A facial movement rarely arrives by itself in a conversation. Listeners also hear words and tone, see posture and timing, and bring expectations about the setting and relationship. In “Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing,” Wieser and Brosch review experiments in which verbal, visual, and auditory information changed how people perceived facial expressions. They also discuss the scene and information held by the observer. A face carries information, but accompanying cues shape its interpretation.
Consider an unnamed project discussion: after a proposed change, a colleague pauses, looks down, and answers briefly. Those actions are observable; “they are annoyed with me” is an interpretation. The pause could reflect a need to think; the short answer could concern the proposal, limited time, or something unrelated to the exchange. No one cue settles which explanation is right. A clear expression may signal emotion without identifying its cause, target, or practical meaning. Treating it as a complete account risks answering a guess as if it were spoken.
This difference helps explain what controlled tests gain and what they leave out. An isolated photograph or posed expression lets researchers compare responses under consistent conditions. That control helps when studying reactions to a defined stimulus. But the test removes the voice, posture, timing, scene, and relationship that shape interpretation at work. A result from a face-labeling task therefore describes performance under that task’s conditions; it cannot simply be carried over to a conversation with more information and different demands.
The 2025 Affective Science article “Faking It Isn’t Making It: Research Needs Spontaneous and Naturalistic Facial Expressions” makes a related distinction between studying responses to an expression and testing whether a person correctly inferred the expresser’s internal feeling. They argue posed stimuli can be mistaken for accuracy tests, even when the task records only viewers’ responses to the display. Naturalistic expressions better resemble everyday interaction, but varied settings and accompanying information make it harder to isolate why someone responded as they did. More resemblance to work does not automatically produce a simpler answer key.
Labels also need care across people and settings. Russell’s critical review, “Is There Universal Recognition of Emotion From Facial Expression? A Review of the Cross-Cultural Studies,” identifies methodological concerns in cross-cultural studies, including the effects of forced-choice labels and posed photographs. The review does not show that facial expressions carry no information or close the debate. It cautions against assuming everyone uses a label the same way or that test categories capture every local meaning. When the cue is ambiguous, describe what you noticed before naming an emotion. A clearly stated concern gives more direct evidence about what the speaker wants addressed than an inferred feeling does; an uncertain cue calls for a slower interpretation and, when useful, a neutral question.
Sources: Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing; Faking It Isn’t Making It: Research Needs Spontaneous and Naturalistic Facial Expressions; Is There Universal Recognition of Emotion from Facial Expression? A Review of the Cross-Cultural Studies
Does a workplace-oriented test get closer to the conversation?
A workplace-oriented test can bring the task closer to situations people encounter at work, but the phrase should be read literally: the test presents work-related material under designed conditions. The Geneva Emotional Competence Test (GECo) makes this distinction visible. Its emotion-recognition subtest uses video clips of actors; other parts ask respondents to judge options in workplace scenarios. The result can say something about performance on those video cues or designed decisions. It cannot show what a colleague felt in a conversation the test never observed. GECo separates four components rather than treating every item as face reading. Recognition is assessed with actor videos. Emotion understanding, regulation in oneself, and management of others use situational-judgment items based on work-related scenarios. In this task, respondents choose among responses to a described situation. It brings role demands into the question, but offers alternatives authored in advance rather than the words, pauses, history, and follow-up of an actual exchange. That distinction matters when a score is translated into a claim. Video recognition supports a claim about interpreting the expressions and response format sampled in those clips. A scenario item supports a claim about selecting a response under its framing and scoring rule. Combining components may describe a broader set of measured competencies, but a profile should not be renamed “accuracy at reading colleagues.” The components ask related, not interchangeable, questions. The GECo instrument-development paper, “The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence,” reports five studies with 888 participants in total. Its abstract says all four subtests showed high measurement precision under Item Response Theory and correlated in expected ways with other emotional-intelligence tests, cognitive intelligence, personality, and demographic variables. It also reports prediction of performance on computerized assessment-center tasks in a sample of professionals, and incremental explanation of students’ academic performance above another ability-based emotional-intelligence test. These results give the measure workplace relevance: designed tasks related to specified measures in those studies. They do not establish that a respondent can identify a particular colleague’s private feeling in an unscripted conversation, or that the same relationships hold for every occupation. The University of Geneva Swiss Center for Affective Sciences’ GECo page describes it as workplace-built, with scenarios and items based on situations that could occur at work, including interviews with managers and professionals during development. It says scoring draws on theory, expert judgments, and general-population consensus. This is a defined basis for scoring designed items, not an account from the person in a live exchange. In a real conversation, the speaker may clarify that an apparent concern was about timing or missing information. A workplace-oriented measure gets closer by matching some stimuli and decisions to work. That makes it more relevant to task performance than an isolated face-labeling item alone, while still leaving a gap between resemblance and replication. For development, choose a measure whose task matches the skill you want to examine, then keep the conclusion at that level. A video-recognition result concerns video cues; a scenario result concerns choices offered in that scenario. Neither supplies the history or the other person’s account needed to settle what happened in one conversation.
Sources: The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence; Geneva Emotional Competence Test (GECo)
What does workplace evidence establish—and what does it leave open?
Workplace relevance is possible: a measured recognition skill can relate to defined work ratings or assessment outcomes. Those relationships show that a task may capture something useful for particular criteria. They do not establish that a reader correctly identified one colleague’s emotion in one conversation. The distinction is between criterion association, where a test result relates to a separately measured outcome, and event verification, where the question is what a person felt during a specific exchange. Research can support the first without answering the second.
In “Predicting Workplace Outcomes From the Ability to Eavesdrop on Feelings,” Elfenbein and Ambady studied 69 employees in a U.S. organization. Participants completed the Diagnostic Analysis of Nonverbal Accuracy (DANVA), which tests recognition of facial and vocal expressions; colleagues and supervisors supplied workplace performance ratings. The researchers reported an interaction between nonverbal channel and emotional valence: recognition of positive emotion was associated with higher ratings, while recognition of negative emotion was associated with lower ratings. The pattern varied by channel, and the result for sadness was not significant. This is a useful complication to the assumption that greater recognition accuracy must always accompany better workplace evaluations. The study links measured task performance with ratings in one organizational setting; it does not show that recognition caused those ratings, or that a test can verify any particular coworker’s feeling. Its age and setting also limit how far the finding can be carried to current workplaces.
The Geneva Emotional Competence Test (GECo) provides a different kind of workplace evidence. Its recognition subtest uses videos of actors, while its emotion-understanding, self-regulation, and emotion-management subtests use situational judgment items based on work scenarios. The original report describes five studies with 888 participants in total. It reports high measurement precision across subtests, expected correlations with other emotional-intelligence tests, cognitive intelligence, personality, and demographic variables, prediction of performance in computerized assessment-center tasks among professionals, and incremental explanation of students’ academic performance beyond another ability EI test. These are separate results for specified tasks and criteria. In particular, performance on a computerized assessment center is not the same outcome as reading a colleague in an unstructured conversation.
Together, the studies make a credible case that emotion-recognition tasks can have workplace-relevant associations and that broader scenario tests can examine responses to work-framed problems. This is the strongest counterpoint to dismissing such tests as irrelevant: the measured skill has related to workplace ratings, and GECo’s designed scenarios extend beyond isolated face labels. Yet relevance is not event-level confirmation. A criterion score or rating aggregates performance under its own rules; a colleague’s feeling belongs to a particular moment, with cues, history, and meaning that the test did not sample. The sources support taking task results seriously at their stated scope. They leave open what any individual felt in a live exchange. For that decision, a recognition score may prompt curiosity, but it cannot substitute for checking the interpretation with the person involved.
Sources: Predicting Workplace Outcomes From the Ability to Eavesdrop on Feelings; The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence
Why isn't a test score an answer key for another person's feelings?
A test score summarizes performance across designed items; a real conversation asks what a particular person meant or felt in a particular moment. Those are different questions. A colleague's pause, brief reply, or tightened voice may prompt concern, but a score cannot tell you whether they felt irritated, distracted, worried about the work, or ready to move on. The result describes how the test taker handled sampled cues and a scoring rule. It does not settle what was happening inside another person during an unrecorded exchange.
This gap remains when a measure has workplace relevance. The Geneva Emotional Competence Test (GECo), for example, uses actor videos for emotion recognition and work-related situational judgment items for other competencies. Its development paper reports precision and expected relationships with other measures across five studies involving 888 participants. That evidence concerns performance on those tasks and their specified comparisons. A designed work scenario may resemble some job demands; it does not include the particular speaker, history, stakes, or unplanned details of a meeting. Relevance adds evidence about a test, not a record of a colleague's experience.
Facial expressions are interpreted alongside other information. “Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing” describes how speech, sound, the situation, and an observer's expectations can alter face perception. A test may control some influences to compare responses consistently. In conversation, words, timing, role relationship, and recent events also matter. Removing those details can make a task easier to standardize while leaving fewer grounds for interpreting this exchange.
Workplace associations do not close the gap. “Predicting Workplace Outcomes from the Ability to Eavesdrop on Feelings” reports that relationships between measured recognition and workplace ratings varied by nonverbal channel and emotional valence. This suggests possible workplace relevance within that study. A relation between a test and an external criterion is not verification of a feeling in one event. The colleague's account is more directly relevant to what they meant or experienced, though it can be incomplete or clarified later.
A confident label can carry extra weight when one person has authority over another or expectations differ about how concern should be expressed. Calling a coworker angry may shift discussion from the work to their supposed temperament; reading quietness as disengagement may affect who gets heard. A score cannot supply that evidence. It can prompt reflection on one's own habits: which cues do I notice, and when do I treat an interpretation as fact?
In the exchange, describe what you observed and ask about the practical issue without assigning an emotion: “I noticed the response was brief. Is there a concern about the proposal we should discuss?” The reply may confirm a concern, point elsewhere, or correct the initial reading. Asking gives the other person a chance to state their meaning and supplies information a test item cannot contain. Update your interpretation as the conversation develops. Use recognition skill to notice a cue and stay curious about its meaning, not to decide what another person felt.
Sources: Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing; The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence; Predicting Workplace Outcomes From the Ability to Eavesdrop on Feelings
How can you check an interpretation during a difficult exchange?
Separate what you noticed from what you think it means. “Your answer was brief” describes an observable part of the exchange. “You are angry with me” assigns an emotion before the other person has explained. A neutral check leaves room for the interpretation to change: “I noticed the response was brief. Is there a concern about the proposal that we should discuss?” A conversation contains more than a face. “Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing” reviews evidence that verbal, visual, auditory, situational, and observer factors can shape how a facial expression is perceived. A test that samples a defined cue cannot supply every part of the context in a live exchange. The words just spoken and setting may alter what a cue seems to mean. The review supports treating an emotion label as an interpretation, rather than a direct reading of someone’s inner state. The question should seek information, not confirmation. “You seem frustrated, don’t you?” offers a label and preferred answer. “Was something in the proposal unclear or concerning?” leaves room to name a practical issue, correct your guess, or raise something you had not considered. If the moment is tense, you might add: “I may be reading this wrong, but I want to check what needs attention.” Listen for the correction as closely as you listened to the cue. A colleague might say the concern is about timing, explain that they were concentrating, or confirm that something in the proposal troubles them. Each answer changes what response could help. If you hear a concern, ask what part needs discussion. If your reading was off, acknowledge that and move on. Asking is not a perfect truth test. A person may need time, choose not to discuss a feeling, or describe the issue differently later. Their account is relevant evidence about what they meant and are willing to share; let it inform your response without turning it into another label. Roles and authority can raise the cost of being misread. Calling a colleague “defensive” can turn an uncertain cue into a judgment about character or performance. This sequence is a practical inference from evidence about contextual interpretation, not a promised intervention. Notice one specific behavior, ask an open question about the matter that may need attention, and update your view from the reply. A recognition score may prompt reflection on your own cue-reading habits. In a difficult exchange, check whether you asked rather than presumed, and let the answer change what you do next.
Sources: Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing; Emotional Intelligence: A Theoretical Overview and Directions for Future Research
What should you do with a test result next?
Read the result at the level of the task that produced it. A face-labeling score describes responses to the faces and labels in that test; a work-scenario judgment describes choices among its situations. Neither tells you what a colleague felt in one exchange. Use the result to reflect on your own cue-reading, then choose an observable behavior: notice what was said or done, check what it meant, and revise your response when you learn more.
In an uncertain conversation, a neutral question can open that check: “I noticed the response was brief. Is there a concern about the proposal we should discuss?” It names an observation and leaves room for correction instead of assigning an emotion. Later, consider whether asking changed what you understood. This applies the context evidence reviewed in “Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing”; it is not a promised intervention result.
For broader reflection on your habits, the private 32-item Emotional Skills Profile is a separate educational tool. It covers recent emotional behavior and judgments on authored scenarios; it has no validated norms and does not measure emotion-recognition accuracy. If that reflection would help, explore the [Emotional Skills Profile](/assessment). Use a test result to consider your performance, and conversation to clarify what another person meant.
Sources
- Measuring Emotional Intelligence with the MSCEIT V2.0
Reports expert and standardization-sample agreement on many MSCEIT answers, supporting task-specific scoring claims.
- The Geneva Emotional Competence Test (GECo): An ability measure of workplace emotional intelligence
Describes GECo tasks and reports five studies with 888 participants and results for specified measures and criteria.
- Geneva Emotional Competence Test (GECo)
Official instrument documentation describes GECo's actor-video recognition and work-scenario judgment task formats.
- Faces in Context: A Review and Systematization of Contextual Influences on Affective Face Processing
Reviews how verbal, visual, auditory, situational, and observer context can shape facial-expression perception.
- Is There Universal Recognition of Emotion from Facial Expression? A Review of the Cross-Cultural Studies
Reviews methodological concerns in cross-cultural expression studies while recognizing associations between faces and emotion labels.
- Faking It Isn’t Making It: Research Needs Spontaneous and Naturalistic Facial Expressions
Discusses the difference between posed and naturalistic expression research and the challenges of interpreting each.
- Predicting Workplace Outcomes From the Ability to Eavesdrop on Feelings
Reports workplace-rating associations that vary by nonverbal channel and emotional valence in the studied organization.
- Emotional Intelligence: A Theoretical Overview and Directions for Future Research
Included in the planned section sources for contextualizing practical interpretation and limits of workplace emotional-intelligence evidence.
Apply it to the real situation
Turn emotional-skill reflection into a practical next step
From this guide: A recognition score describes performance on its sampled task; it cannot settle what a colleague felt in one conversation.
If you want to reflect on your own emotional habits beyond a recognition task, the private 32-item Emotional Skills Profile offers a separate educational reflection tool covering recent emotional behavior and judgments on authored scenarios. It has no validated norms and does not measure emotion-recognition accuracy. Explore it as a starting point for personal reflection, then use conversation to clarify what another person meant.